1.4Latency vs Throughput
Understanding Little's Law, tail latency amplification (p95/p99), queuing theory, and the tension between batching and responsiveness.
Gangs of Developers Editorial Team
Distributed Systems & Software Architecture Blueprint SeriesKey Takeaways
Latency is the time to complete a single operation (ms), whereas Throughput is the number of operations completed per unit of time (QPS / MB/s).
Average latency is a lie: p99 and p99.9 tail latencies dictate real user experience, especially in microservice fan-out trees where slow tails compound.
By Little's Law (L = λW) and queuing theory, as resource utilization approaches 80-90%, queuing delay causes latency to spike exponentially even while throughput plateaus.
System Architecture Diagram
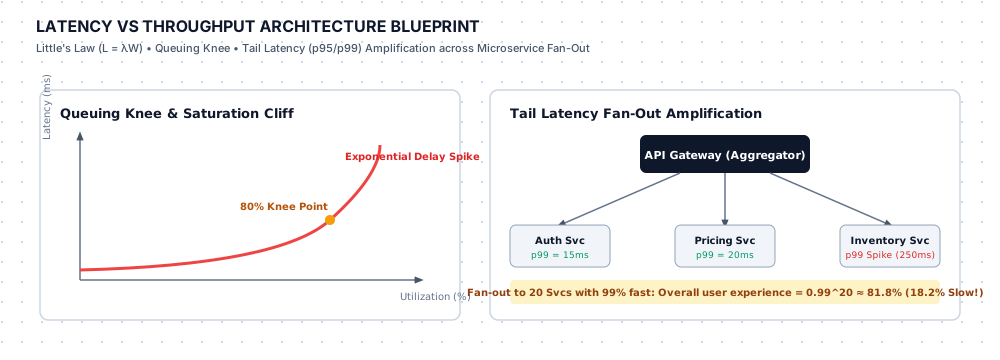
Little's Law, Queuing Theory, and Tail Latency Amplification
Latency measures how long a single request takes from client dispatch to response receipt. Throughput measures how many requests a system processes per second. Little's Law states L = λ × W (Concurrent requests in system = Arrival rate × Mean response time). When arrival rate approaches the system's maximum processing rate, requests sit in queues, causing latency to skyrocket non-linearly. Worse yet, in a microservice architecture where 1 user request fans out to 20 parallel backend services, even if each service has a 99% chance of responding fast (<10ms), the probability that ALL 20 respond fast is 0.99^20 = 81.8%, meaning nearly 20% of user requests experience tail latency!
p50 (Median): Half of requests are faster. Masks severe outliers.
p99 / p99.9 (Tail Latency): Caused by GC pauses, noisy neighbors, TCP retransmits, cache misses, and disk compaction.
Hedged Requests: Send the same read request to a second replica if the first doesn't respond within the p95 threshold to chop off the p99 tail.
| 1 | export async function hedgedRead<T>( |
| 2 | primaryCall: () => Promise<T>, |
| 3 | backupCall: () => Promise<T>, |
| 4 | p95TimeoutMs = 15 |
| 5 | ): Promise<T> { |
| 6 | return new Promise((resolve, reject) => { |
| 7 | let settled = false; |
| 8 | const timer = setTimeout(() => { |
| 9 | // Primary exceeded p95! Fire backup replica concurrently |
| 10 | backupCall().then((res) => { |
| 11 | if (!settled) { settled = true; resolve(res); } |
| 12 | }).catch(() => {}); |
| 13 | }, p95TimeoutMs); |
| 14 | |
| 15 | primaryCall().then((res) => { |
| 16 | clearTimeout(timer); |
| 17 | if (!settled) { settled = true; resolve(res); } |
| 18 | }).catch((err) => { if (!settled) reject(err); }); |
| 19 | }); |
| 20 | } |
Trading Latency for Throughput via Batching
Many high-scale systems intentionally sacrifice a few milliseconds of latency to achieve massive gains in throughput. Instead of performing a network round-trip and disk fsync for every single message, systems like Kafka and group-commit databases buffer records for 5-10ms (or up to 64KB) and flush them in a single sequential I/O operation.
Micro-batching (Kafka linger.ms): Waits 5ms to coalesce 500 messages into 1 compressed TCP packet, boosting throughput 10x.
Pipelining (Redis): Sends 50 commands in a single socket write without waiting for individual RTTs.
Asynchronous Offloading: Return 202 Accepted in 5ms to keep user latency low, and process heavy work via background worker queues.
Architectural Trade-Off Matrix
Evaluating production alternatives, concurrency bottlenecks, and operational costs.
| Approach / Option | ✓ Key Advantages | ⚠ Trade-Offs & Bottlenecks | ★ Best Suited For |
|---|---|---|---|
| Optimize for Ultra-Low Latency (No Batching) | Immediate per-request completion, ideal for interactive user-facing request/response loops. | High per-message syscall, network header, and disk IOPS overhead; saturates CPU and network cards at lower QPS. | Real-time bidding (RTB), gaming servers, interactive UI APIs, and high-frequency trading. |
| Optimize for High Throughput (Micro-Batching & Compression) | 10x-50x higher records/sec per core, sequential disk writes, high compression ratios across batch payloads. | Adds a deterministic baseline latency floor (linger.ms wait time) to every single item. | Log ingestion, telemetry pipelines, Kafka producers, analytics warehouses, and database group commits. |
GOD System Design Interview Pro-Tip
Never say 'latency should be under 100ms.' Always specify the percentile: 'We will target p50 read latency under 20ms and p99 read latency under 100ms.' This immediately signals senior production experience.